Managed data operations
Human judgment.
Work you can trust.
Trained teams review AI output, verify documents and product data, and annotate the images, video and sensor data behind computer vision and robotics, inside your tools, with a named lead and every correction explained.
$5 per person-hour for standard tasksTeam management and QA included
Specialized annotation and enterprise work is scoped and priced separately by the enterprise team.
Illustrative review example
Illustrative example, automotive aftersales support. Not a real customer record.
Why teams trust us with their work
Deepen AI has delivered annotation and data services for Daimler, BMW, Bosch, Mercedes, Honda, Hexagon, Aptiv and Ford Otosan.
- 8+ years running a managed annotation team for automotive and robotics customers
- Co-author of the ASAM OpenLABEL standard
- SOC 2 Type II and ISO 27001 as Deepen AI company certifications, scoped to the services delivery team
- A known, trained team. Not an anonymous crowd.
What we do
Judgment you can point to.
Illustrative review example
- Groundedness
- 1 / 3
- Completeness
- 2 / 3
- Policy accuracy
- 1 / 3
- Total
- 4 / 9, needs correction
What changed and why: added the diagnostic-report requirement before promising a remedy. The draft skipped the one condition that gates the claim.
AI output review
A trained reviewer checks the AI's draft answer against the cited source passage and a scoring rubric, then corrects it with a one-line reason. Illustrative rubric for a single example, not a performance metric.
See how we check quality →What the work looks like
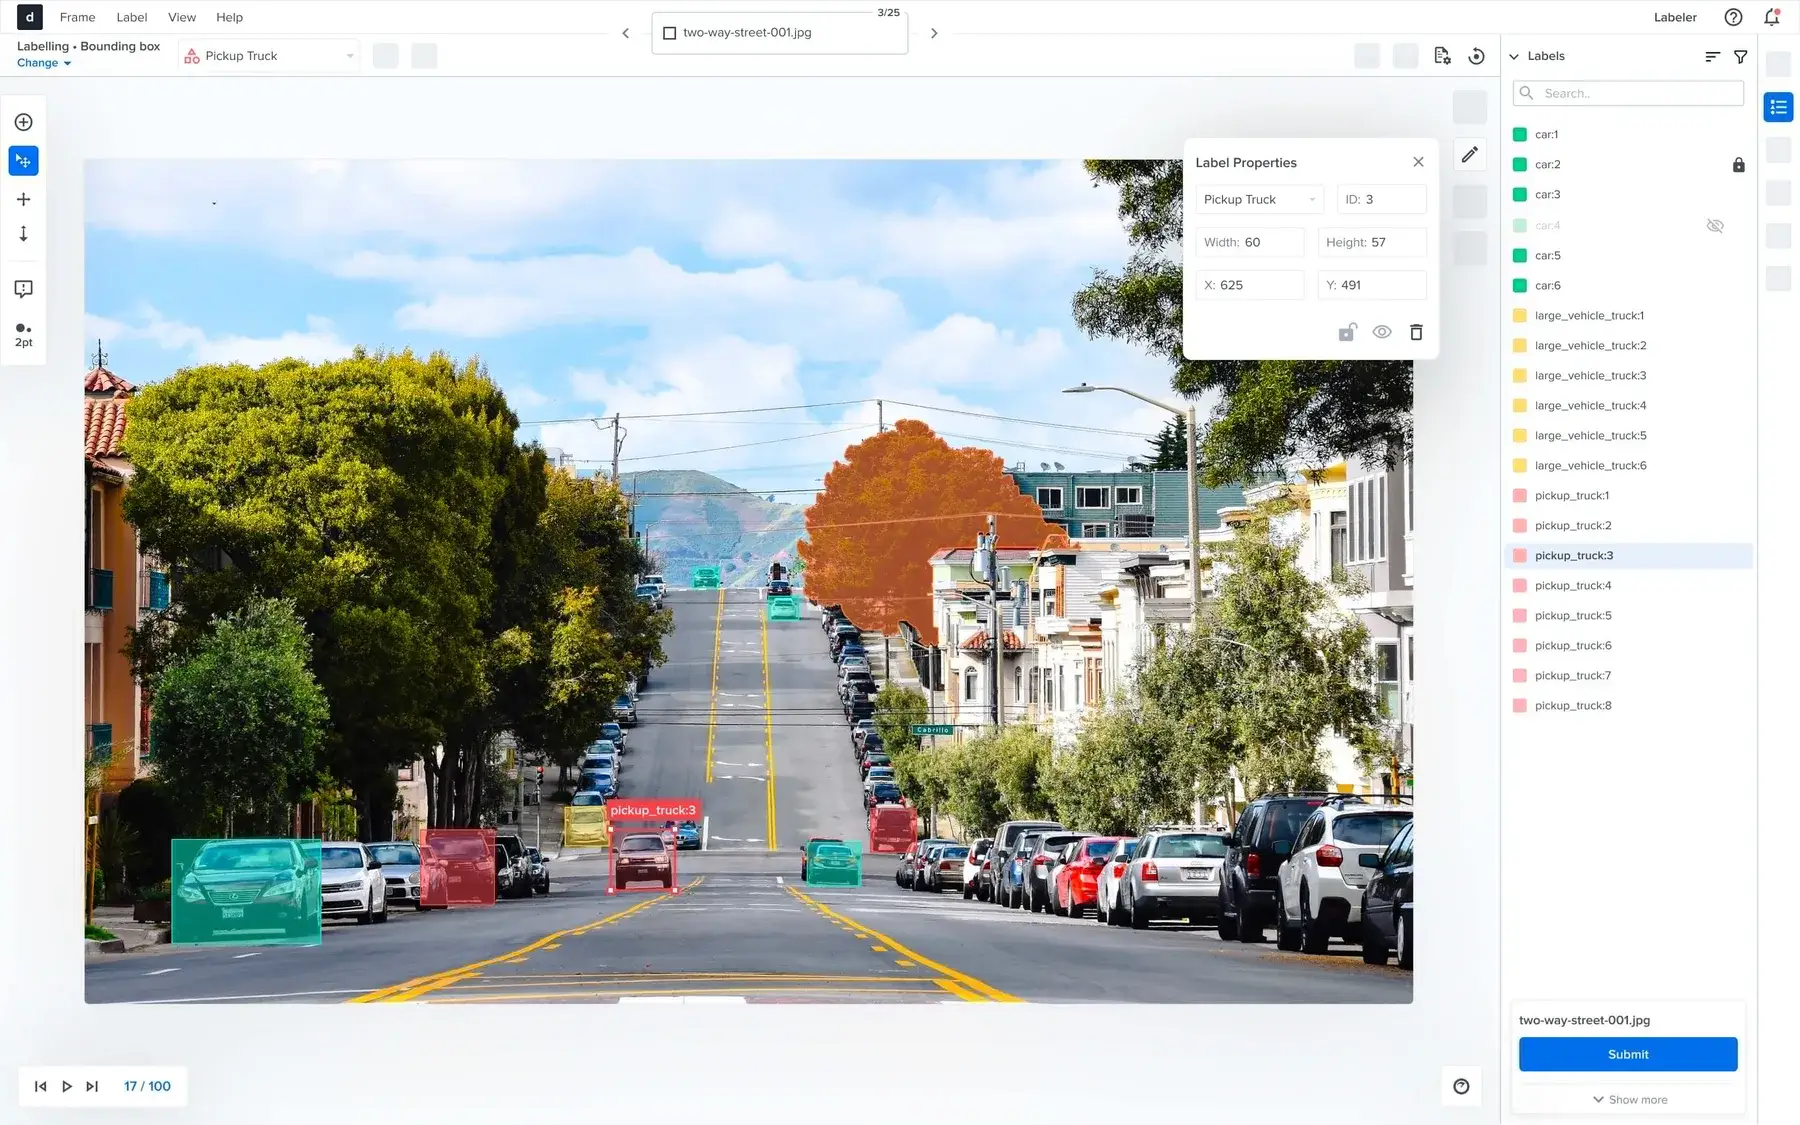
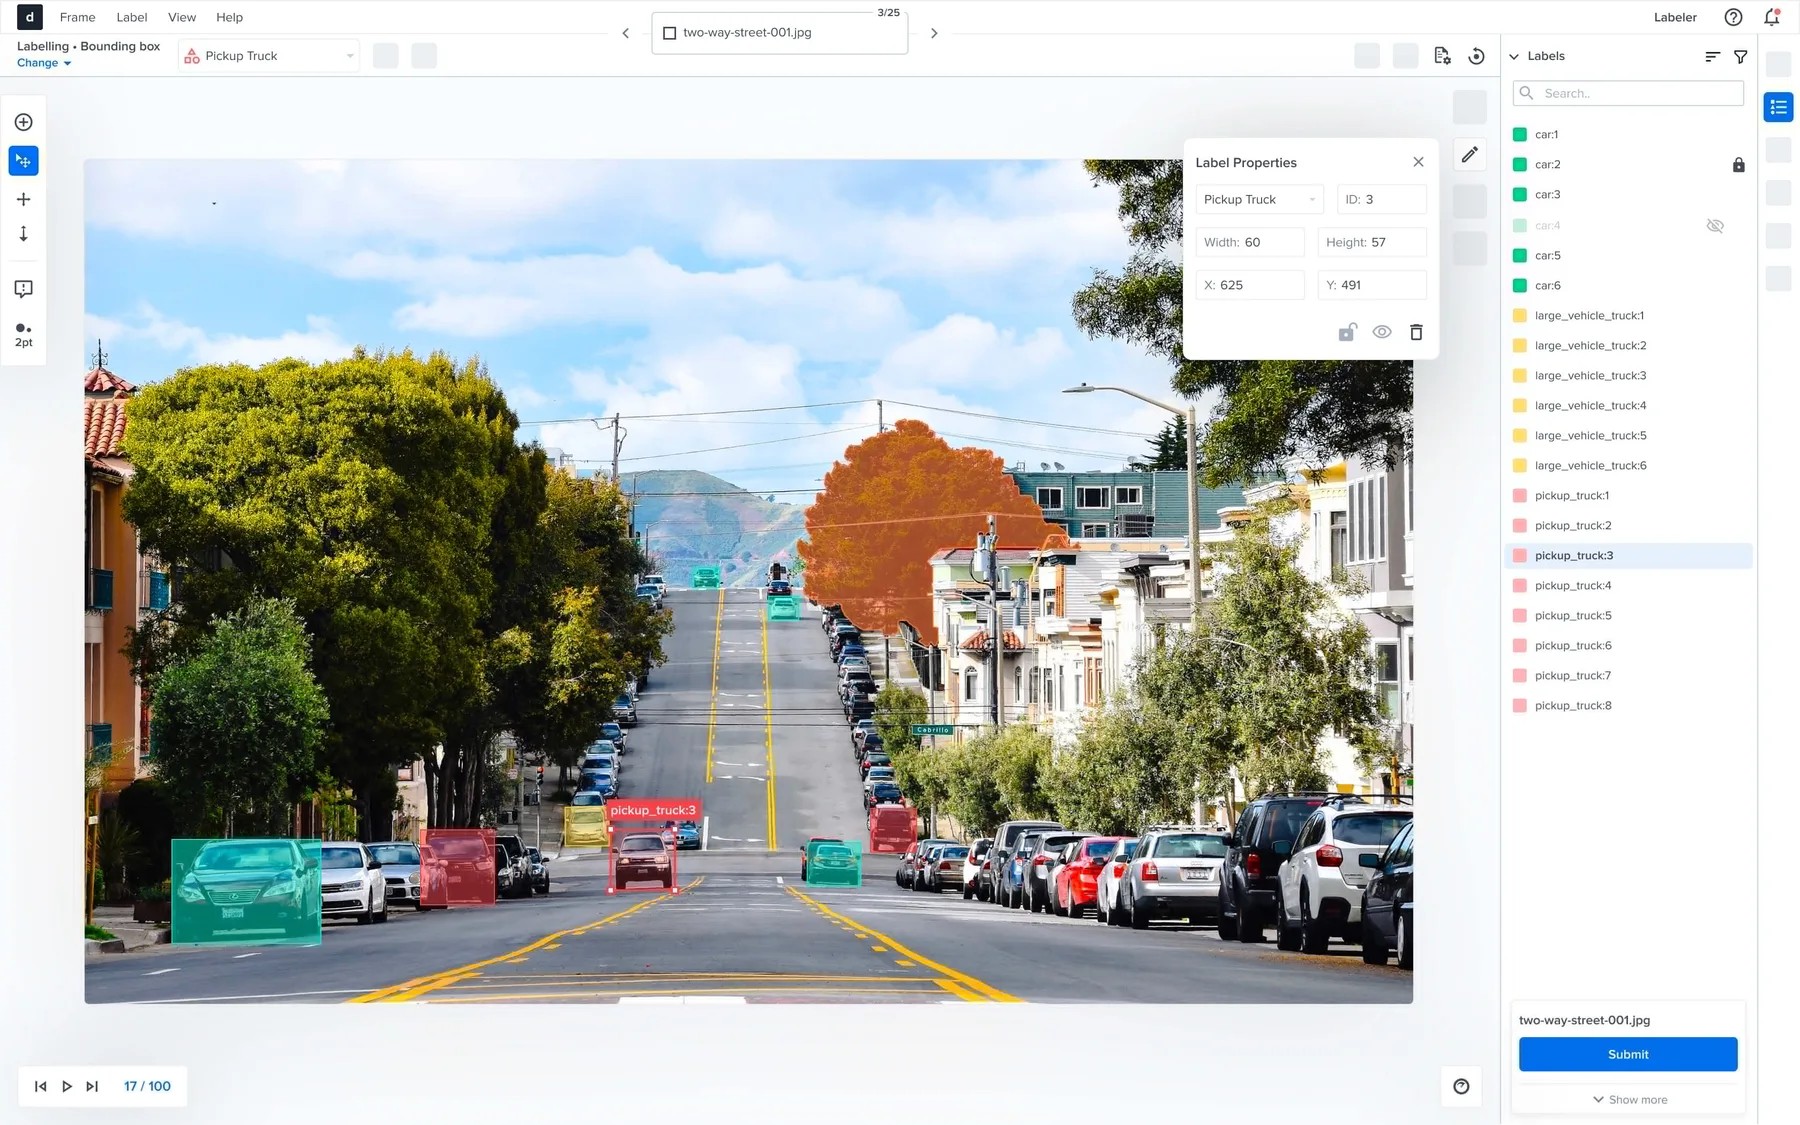
Annotation, inside Deepen AI’s own tools.
Image, video, lidar and multi-sensor annotation for computer vision, automotive and robotics, built over 8+ years, with Deepen’s own tooling and a trained annotation team.
Illustrative: Deepen AI's own tooling
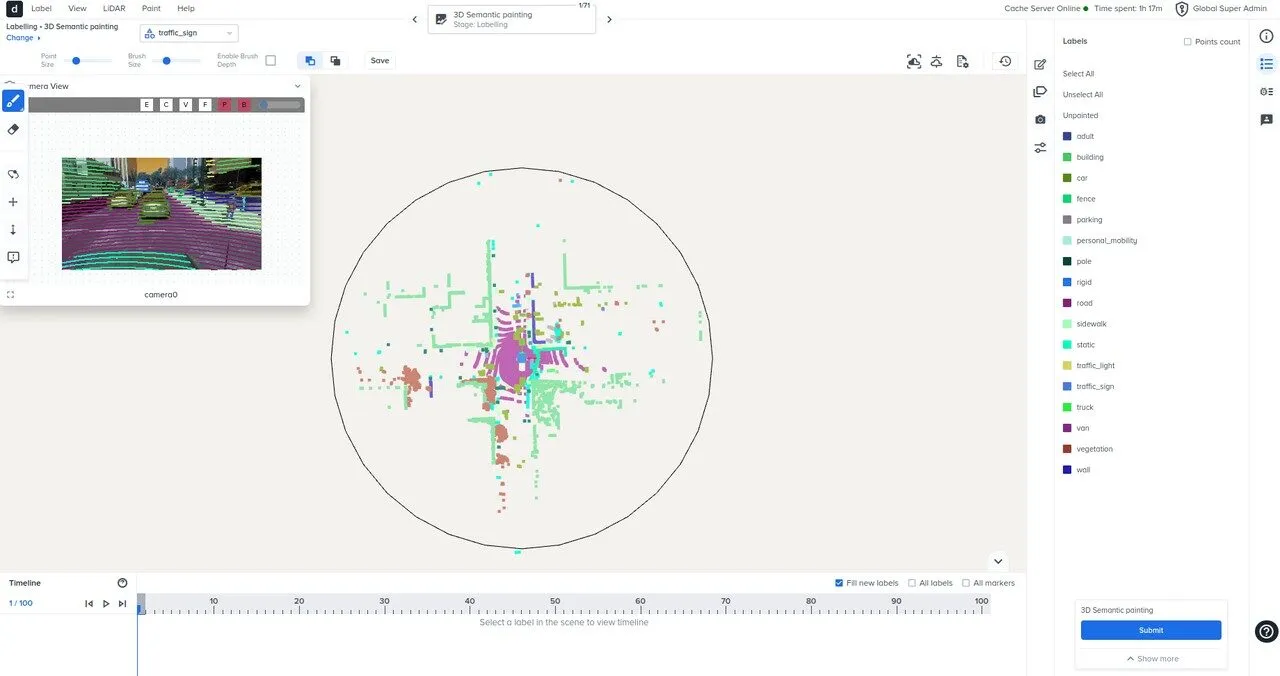
Illustrative: Deepen AI's own tooling
How it works
Four steps. You keep your tools and your data. We bring the people and the process.
Share the task and examples
Tell us the task. Share your guidelines and a few finished examples. Create accounts for our people in the tools you already use.
Agree scope and train the team
We pick people for your task and train them on your guidelines and examples before they touch live work.
Deliver with a named lead and QA
A named team lead runs the day to day and is your contact. QA reviewers check a sample of finished work against your guidelines and known-correct answers.
How we check quality →Review results and continue or adjust
Every week you get hours worked, output, QA results, open questions and what changes next week.
What a weekly report looks like
What a weekly report looks like
Every week your team lead sends a short report like this one. It shows what people did, what QA sampled, what went wrong and what we need from you.
- Hours worked
- 118 person-hours
- Items completed
- 2,360. Each item was reviewed by one trained reviewer.
- Items QA-sampled
- 236 (10% of completed). A QA reviewer re-checked these against the rubric and gold set.
- Acceptance rate on the sample
- 95.8% (226 of 236)
- Error categories in the sample (10)
- scored "correct" when the answer missed a required step (6) · missed a refund policy check (3) · formatting (1)
- Rework
- the 10 sampled errors were corrected. The policy errors pointed to one topic, so 140 more refund answers were re-checked. 4 more were corrected.
- Open questions for you (2)
- Should answers that quote the old 60-day refund window be scored "wrong" or "partly correct"? Are Spanish-language chats in scope?
- Next week
- refund rule added to the guidelines. 20 new gold items for refund questions.
Every item is done by one trained person. QA reviewers check a sample, not every item. The report always shows how many items were sampled.
How we check quality →Priced on the page
team lead and QA sampling included
Know your rate and what it includes before you book a call. The rate covers a trained person, a named team lead, QA sampling and a weekly report.
See pricing →Specialized annotation for computer vision, automotive and robotics (image, video, lidar and multi-sensor) is scoped and priced separately by the enterprise team, never at the $5 standard-task rate.
Discuss an enterprise projectFAQ
What kinds of tasks do you take?
Repeatable data work inside your tools. Most teams start with AI output review, text annotation, document data extraction, product data enrichment or data entry. We also take other online work in English, listed on the services page. We do not take phone support or graphic or violent content moderation.
What does $5 per person-hour include?
One trained person on your task, plus a named team lead, QA sampling and a weekly report. It applies to the standard tasks listed on the pricing page. Other work is quoted after we see a sample.
Do I need a sales call?
No. Sign up with your work email and describe the task. Our ops team reviews it and emails you a pilot plan with a quote: people, hours, start date and price. If you want a call, ask for one.
How does the two-week pilot work?
It is prepaid at the quoted amount: people × hours per week × 2 weeks × $5, with at least 20 hours per person per week. You pick the task. We train the team, run real work for two weeks and send a report each week. Then you decide whether to continue.
Who does the work?
Trained members of the Deepen AI team, led by a named team lead. We aim to keep the same people on your work, so they learn your rules.
How do you check quality?
One trained person does each item. QA reviewers re-check a sample, not every item, against a gold set of known-correct examples built from your guidelines. Hard cases go up a review tier. The weekly report shows how many items were sampled and what QA found. It is the same process we use for our annotation work.
How we check quality →Is my data safe?
Our people work inside your tools, on accounts you control and can switch off. Deepen AI holds SOC 2 Type II, ISO 27001 and TISAX, and follows GDPR. We sign your NDA. See the security page for details.
We used MTurk or Amazon A2I. Can you help?
Yes, for business and data tasks. We can join your Ground Truth or A2I labeling portal as a private workforce, so your pipeline stays the same. For academic surveys and research participants, Prolific or CloudResearch are a better fit.
Start with one workflow.
Tell us what needs doing. We’ll send a pilot plan with the team, hours, scope and price.