AI evaluation
before and after release
Deepen AI's trained raters score your model and agent against your rubric, try to break them, and turn what they find into tests you can run again.
A plan within 2 working days. No sales call.Shipping an agent?
Services
LLM evaluation
Your model's outputs scored against your rubric, with a reason for each score.
AI agent evaluation
What your agent actually did, checked step by step, not just what it said.
AI red teaming
People try to break your model or agent before release, and log what worked.
RLHF preference data
Side-by-side comparisons and ratings from trained raters, for model training.
Custom benchmarks
Test sets and regression suites built from your real failures.

How it works
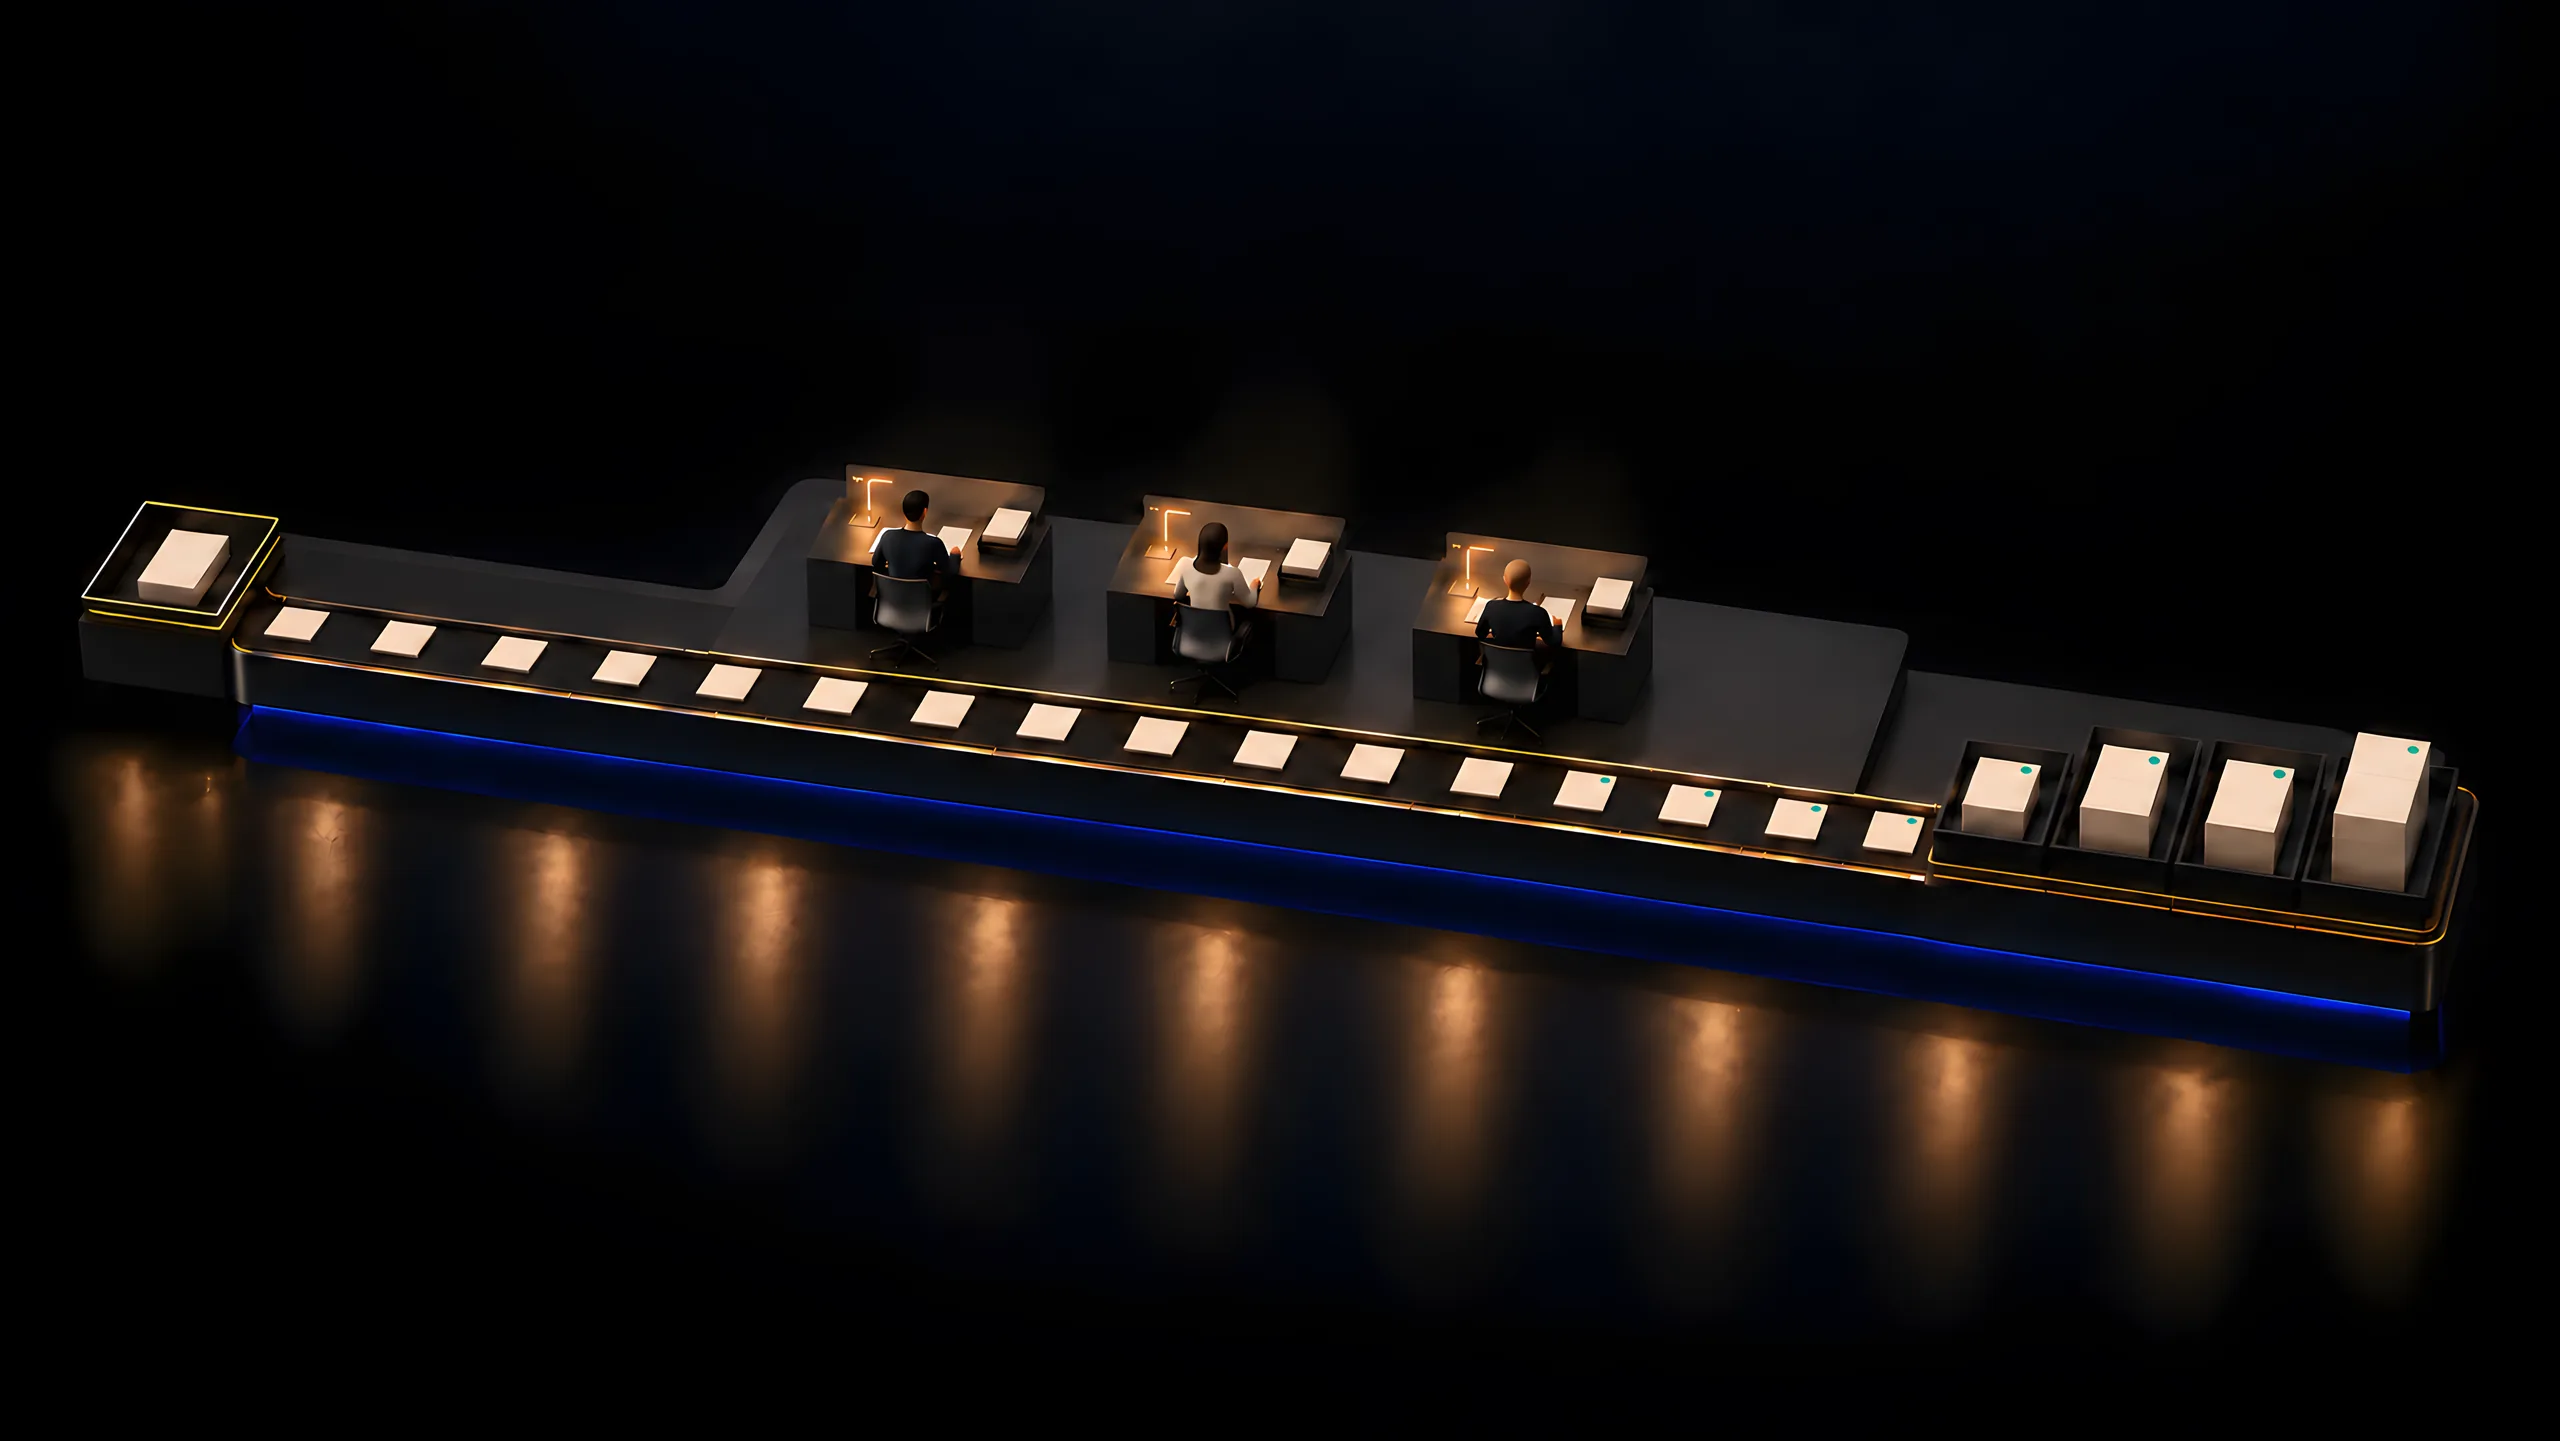
Your test set goes in. Trained raters score every output against your rubric. You see where your AI is strong and where it fails.
In your evaluation tool
Raters score in your eval platform or labeling tool, on accounts you control.
In a shared sheet
Your outputs arrive in a spreadsheet; raters add scores and reasons in the columns you set.
In Ground Truth
As a private workforce on your existing SageMaker Ground Truth jobs.
How we keep quality high
Every reviewer's accuracy is measured
Items you've already answered are hidden in the real work, so we know how accurate each person is.
Nobody guesses on unclear cases
The team lead decides, or asks you. Your answer joins the guidelines.
You see the results every week
A weekly report shows work done, QA results and what's improving.
Pricing
AI evaluation is quoted in your plan, because the rate depends on the expertise and turnaround the work needs. Your plan shows the rate, the hours and the total price before you pay anything.
Tell us the task. What your AI produces, and your rules.
Get a plan and a price within 2 working days.
Run a two-week pilot on real items, with two weekly reports. Then decide.
Questions
We already use automated evals. Why add people?
Automated judges are fast, but they miss what they weren't built to catch, and they need checking themselves. Trained raters score the outputs that matter most, and their scores show how far you can trust your automated judge.
How do you keep scores consistent between raters?
Every rater scores the same known items before live work, and we check how often they agree. Known items stay mixed into the work, and agreement is reported every week.
Can raters with domain knowledge do the work?
Tell us the domain when you request a plan. The plan says who will rate your outputs, and the rate, before any work starts.
Can we run the same evaluation after every release?
Yes. Keep the test set and rubric fixed, and the team scores each new version the same way, so results compare from one release to the next.
Do our model outputs stay confidential?
Yes. We work under NDA, inside your tools, with the access you set. Deepen AI holds SOC 2 Type II, ISO 27001, ISO 9001 and TISAX.